
High-Throughput Data Integration Services in Bangalore
We break down enterprise data silos by integrating diverse data sources across SAP, Salesforce, Oracle, legacy mainframes, and modern SaaS platforms. Build resilient high-throughput data connectors with automated schema sync and zero data loss.
Complete Data Integration Capabilities
Seamlessly connecting distributed enterprise databases into a single verified truth.
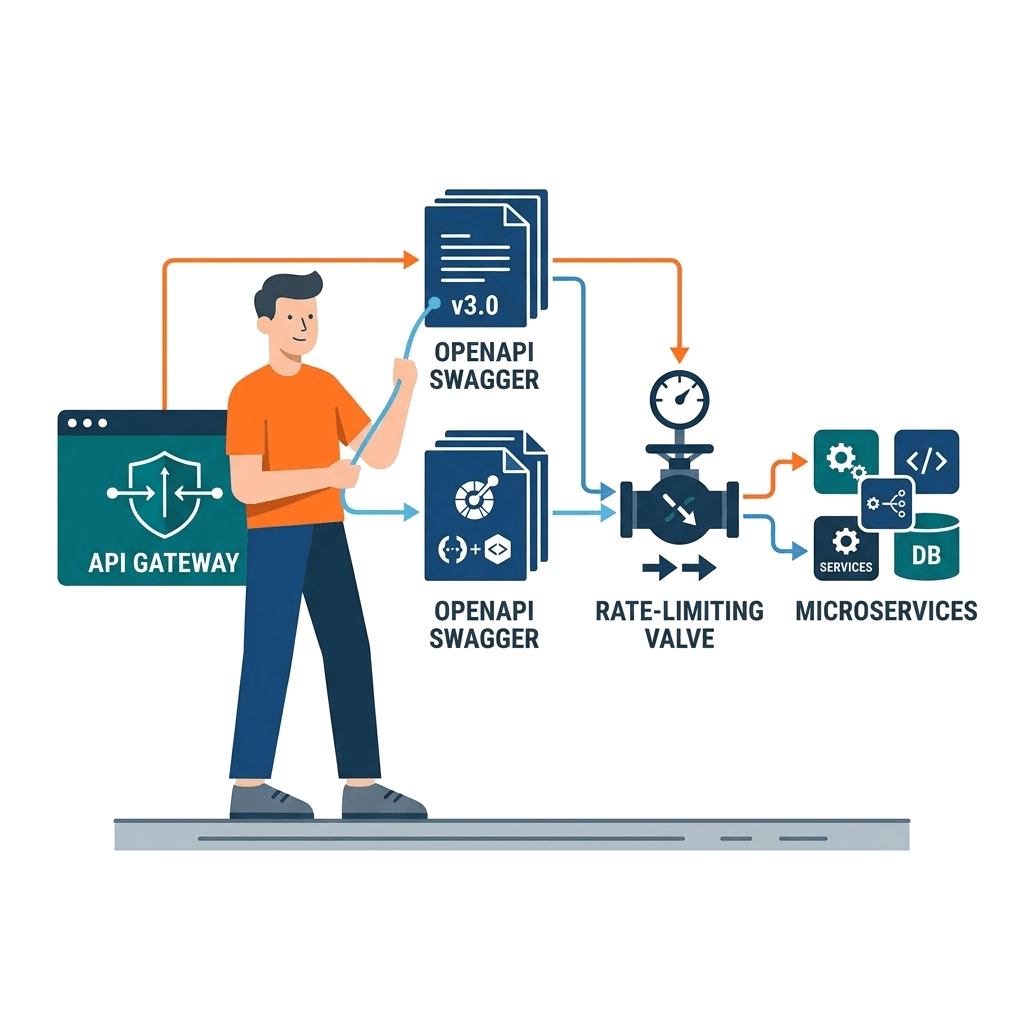
Enterprise ERP & CRM Ingestion
Automated high-throughput extraction from SAP S/4HANA, Salesforce, NetSuite, Microsoft Dynamics, and Oracle Financials.
Explore Enterprise ERP & CRM Ingestion
Open-Source & Managed ELT Connectors
Deploying self-hosted Airbyte clusters and managed Fivetran pipelines synchronizing hundreds of external SaaS APIs automatically.
Explore Open-Source & Managed ELT Connectors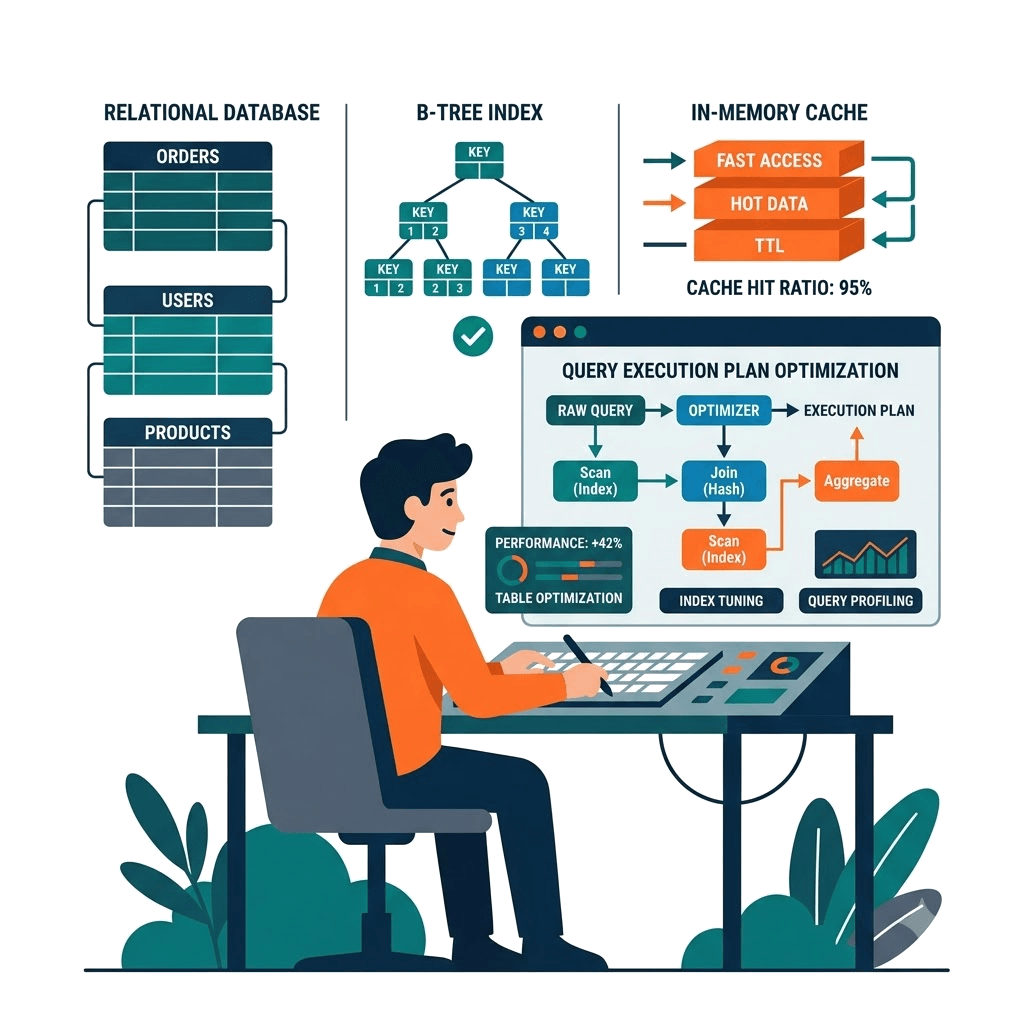
Log-Based Change Data Capture (CDC)
Low-latency database synchronization capturing row-level changes from PostgreSQL, MySQL, and Oracle without running polling queries.
Explore Log-Based Change Data Capture (CDC)
Automated Schema Drift Resolution
Dynamic schema evolution handling newly added columns, type widening, and payload alterations without pipeline failures.
Explore Automated Schema Drift Resolution
Automated Source-Target Reconciliation
Continuous automated data checksum audits comparing source databases to warehouse destinations to identify missing or altered records.
Explore Automated Source-Target Reconciliation
Legacy Mainframe & File Ingestion
Parsing high-volume SFTP files, mainframe fixed-width flat files, XML dumps, and EDI transactions into modern Parquet formats.
Explore Legacy Mainframe & File IngestionOur Data Integration Toolset
ELT ingestion engines, CDC tools, and data reconciliation platforms.
Ingestion & ELT
Change Data Capture (CDC)
Orchestration & Workflow
Data Quality & Auditing
Our Data Integration Lifecycle
A battle-tested 6-step integration architecture ensuring clean, continuous data delivery.
Source Discovery & API Profiling
Cataloging all enterprise source systems, authentication protocols, rate limits, and historical data volumes.
Integration Architecture & Pipeline Design
Selecting between batch ELT, log-based CDC, or streaming API connectors based on SLA needs.
Historical Backfill & Initial Seeding
Executing parallelized historical data loads without impacting production transactional system performance.
Automated CDC & Incremental Sync
Setting up real-time CDC or high-frequency micro-batch jobs to capture ongoing delta changes.
Data Quality Gating & Schema Evolution
Adding automated validation rules, schema drift handlers, and anomaly detection checks.
Monitoring, Alerting & Reconciliation
Configuring continuous reconciliation dashboards and automated alerts on pipeline sync stalls.
Enterprise Integration Standards
Zero data discrepancies, automated resilience, and regulatory compliance.
100% Data Completeness Guarantee
Continuous reconciliation audits ensuring every committed source record exists at the destination.
Automated Schema Drift Handling
Ensuring new fields in source APIs do not break downstream analytical pipelines.
Sub-15 Minute Freshness SLA
Delivering business-critical data from operational systems to analytical warehouses in under 15 minutes.
End-to-End PII Sanitization
Anonymizing or masking credit card numbers and personal identifiable information during transit.
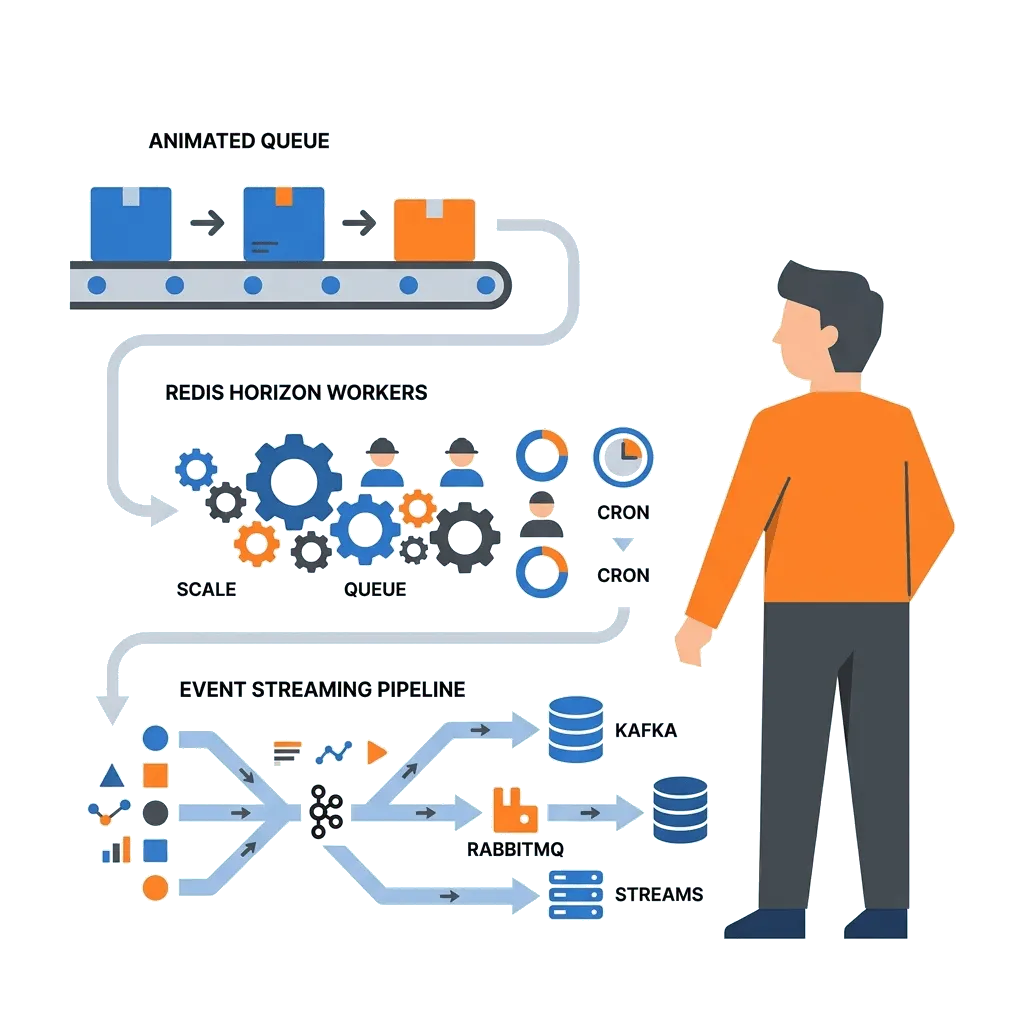
Resilient Retry & Backoff Mechanics
Exponential backoff mechanisms surviving source API rate limit throttling and network hiccups.
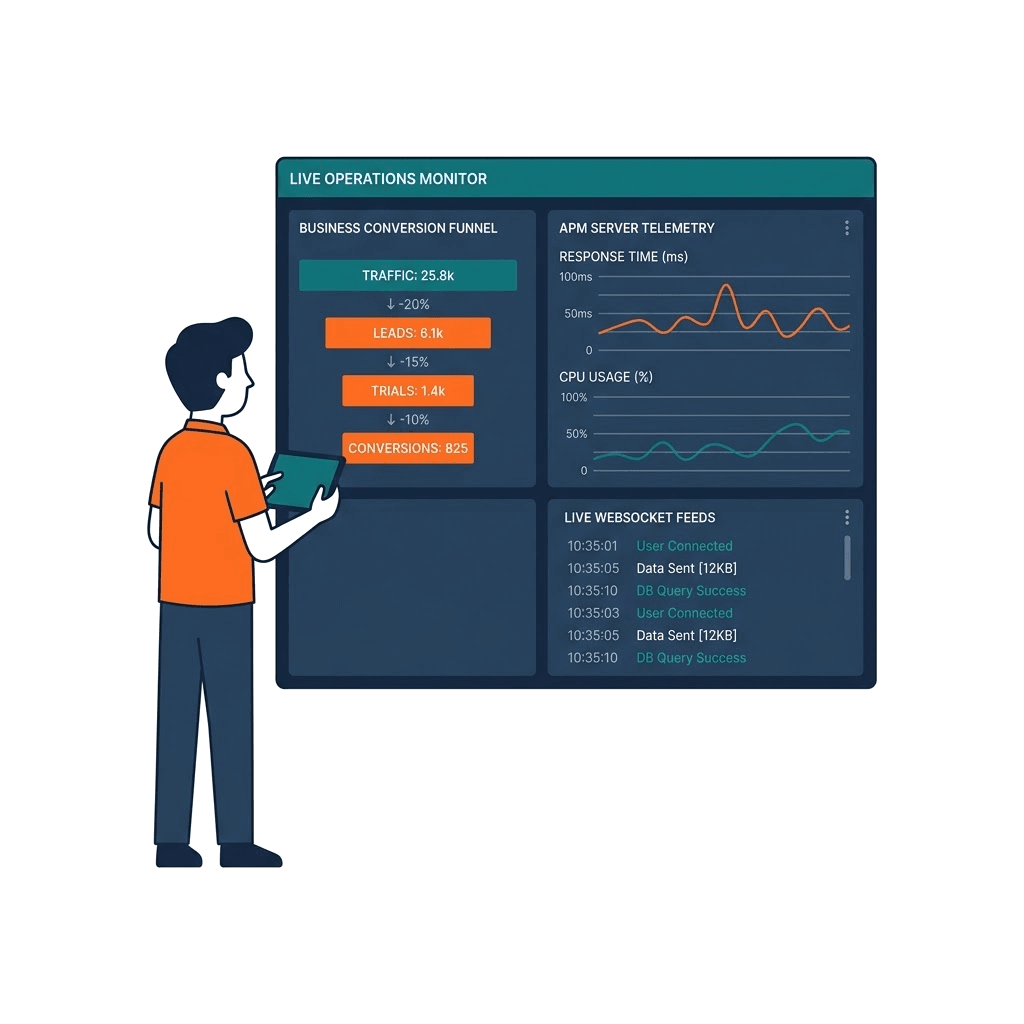
Transparent Sync Status Dashboards
Real-time visibility into table row counts, sync latency, and pipeline execution logs.
Featured Data Integration Case Study
Integrating 38 heterogeneous source systems for a multi-brand retail enterprise.
Omnichannel Data Integration Across 38 Retail & ERP Systems
Architected a unified integration framework using Airbyte and Debezium CDC connecting SAP ERP, Shopify stores, POS terminals, and customer CRM systems into a central Snowflake warehouse. Eliminated manual CSV exports and achieved near real-time 10-minute reporting.
Why Partner With Render Infotech?
Over 16+ years and 500+ successful deployments, we have established an engineering reputation in Bangalore for technical rigor, architectural transparency, and zero compromise on code quality.
- Dedicated In-House Engineers: Direct communication with senior specialists, not junior offshore intermediaries.
- 100% IP & Code Ownership: Full source code, database structures, and copyright ownership transferred upon milestone sign-off.
- Performance SLA Guarantee: Contractually committed speed benchmarks, security verification, and high-availability SLAs.
- Transparent Weekly Sprints: Live staging environments, progress demos, and clear milestone accounting.
Enterprise Performance Commitment
Every project we engineer is guaranteed to pass rigorous vulnerability scans, mobile responsiveness checks, and automated regression testing prior to production launch.
Bangalore Engineering Center
Kalyan Nagar, Bengaluru — Local Support & Global Standards
High-Volume Data Integration Services FAQs
Answers to common technical, pricing, and timeline questions regarding our High-Volume Data Integration Services services.
Ready to Architect Your Solution?
Connect directly with our senior technical architects in Bangalore for an architectural consultation, technology recommendation, and formal scope estimate within 24 hours.
Request a High-Volume Data Integration Services Proposal
Fill out your technical brief below to receive an architectural estimate within 24 hours.