
Enterprise ETL / ELT Pipeline Development in Bangalore
We build reliable, automated ETL and ELT data pipelines that ingest data from hundreds of enterprise sources, execute transformations in cloud warehouses, and deliver clean, verified datasets on schedule. Powered by Apache Airflow, dbt, and modern orchestration engines.
Complete ETL / ELT Pipeline Capabilities
Automating data movement and transformations with resilience and enterprise observability.
Modern ELT Architecture Design
Extracting raw data into cloud warehouses without upfront bottleneck transformations, enabling agile in-warehouse SQL transformations.
Explore Modern ELT Architecture Design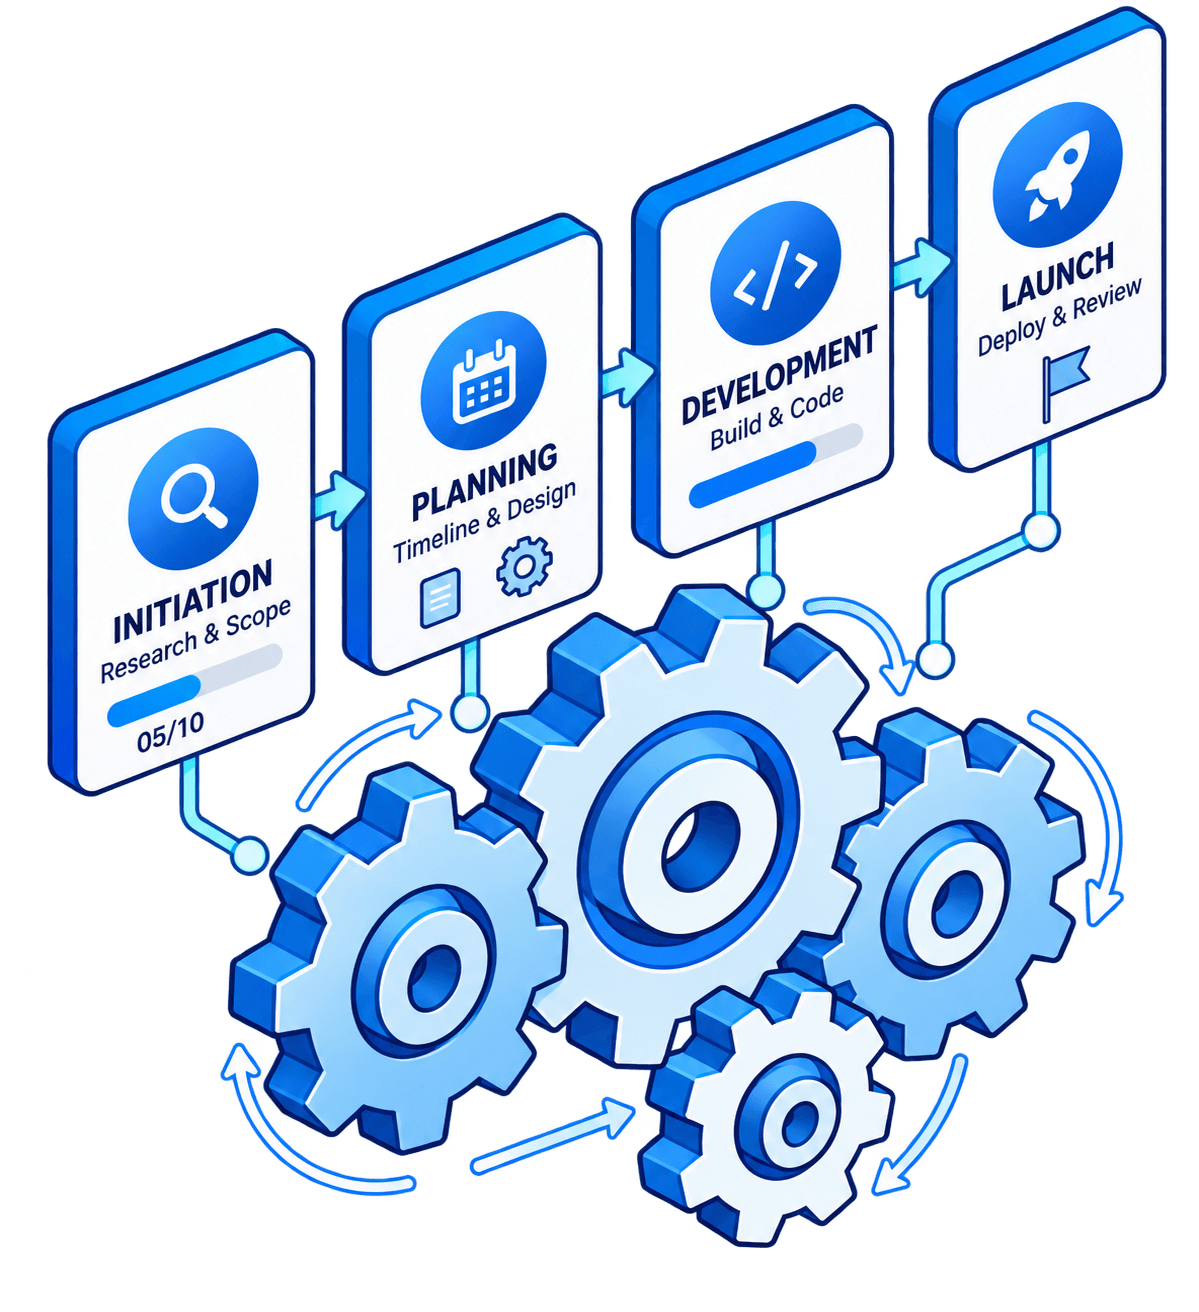
Apache Airflow & Prefect Workflow Orchestration
Building complex DAGs with conditional branching, parallel task execution, automated retries, and SLA timeout alerts.
Explore Apache Airflow & Prefect Workflow Orchestration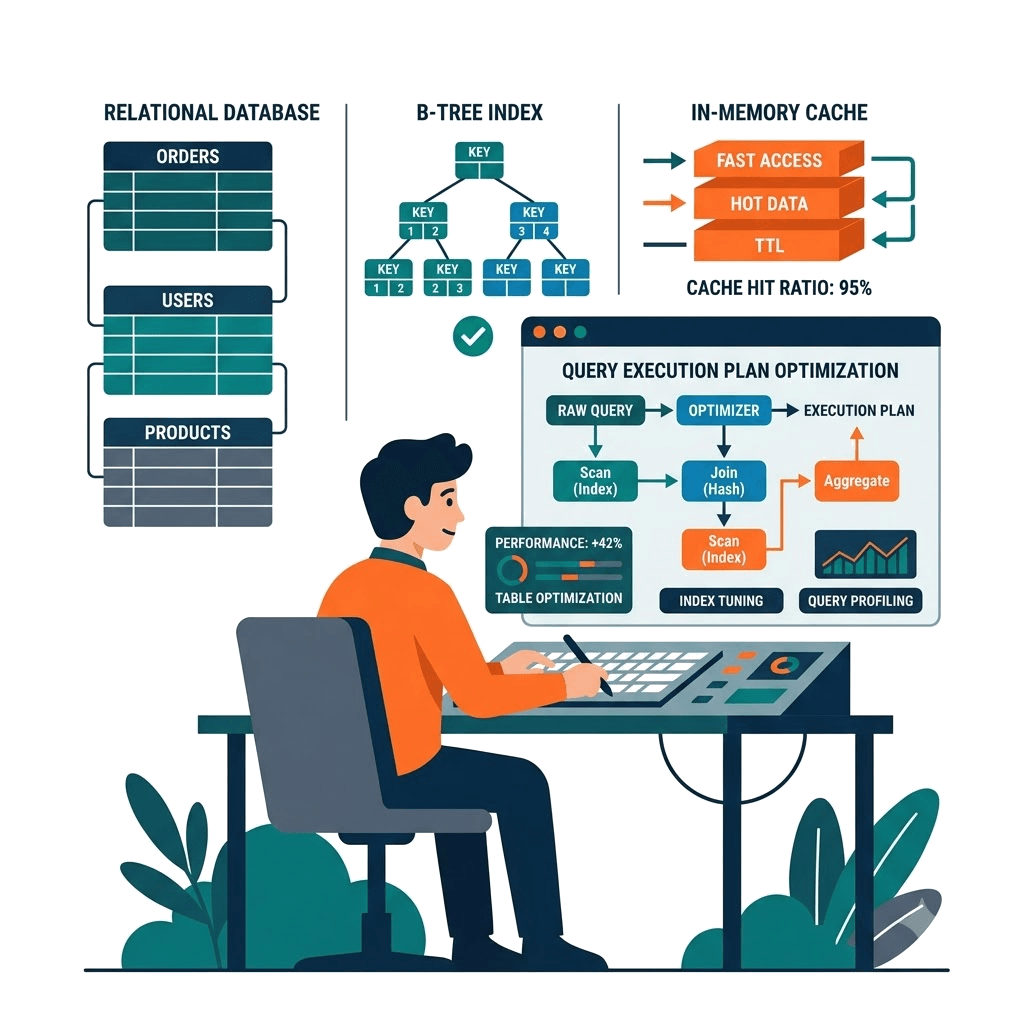
Incremental & Delta Pipeline Processing
Processing only modified or newly created rows using high-watermark timestamps, slashing pipeline execution runtimes by 80%.
Explore Incremental & Delta Pipeline Processing
Reverse ETL & Operational Analytics
Pushing enriched analytical metrics from data warehouses back into operational CRMs (HubSpot, Salesforce) and ad platforms via Census or Hightouch.
Explore Reverse ETL & Operational Analytics
Automated Error Handling & Retries
Resilient exponential backoffs, circuit breakers, and automated data quarantine routes preventing failed jobs from blocking pipelines.
Explore Automated Error Handling & Retries
End-to-End Data Quality Gating
Continuous automated data testing verifying schema types, volume anomalies, null counts, and financial reconciliation balances.
Explore End-to-End Data Quality GatingOur Pipeline Engineering Stack
Workflow orchestrators, transformation tools, and reverse ETL systems.
Workflow Orchestrators
Extraction & Ingestion
Transformation & Modeling
Reverse ETL & Activation
Our Pipeline Implementation Lifecycle
A systematic 6-step engineering methodology guaranteeing data accuracy and high uptime.
Source API & Volume Profiling
Assessing ingestion frequencies, historical backfill requirements, authentication mechanisms, and API limits.
Pipeline Architecture & DAG Design
Designing modular Airflow DAGs, error handling policies, staging bucket structures, and schema registries.
Extraction & Ingestion Implementation
Deploying high-speed extraction connectors with incremental watermark tracking and pagination.
dbt In-Warehouse Transformation
Writing modular SQL transformation layers with automated testing and dependency graph compilation.
Backfill & Historical Reconciliation
Running historical data backfills with checksum verification comparing source system row counts.
Production Deployment & Observability
Configuring automated alerting into Slack/PagerDuty, execution SLAs, and automated maintenance DAGs.
Enterprise Pipeline Standards
Idempotent executions, zero data duplication, and real-time failure alerting.
100% Idempotent Pipeline Design
Guaranteeing that re-running any pipeline run produces identical output without duplicating records.
Incremental Watermark Processing
Processing delta records based on last modified timestamps to keep runtimes fast and resource costs low.
Automated Slack/PagerDuty Alerts
Instant automated alerts delivering stack traces and root causes within 60 seconds of any task failure.
Sub-Hour Freshness SLAs
Ensuring end-to-end extraction, transformation, and warehouse loading completes well ahead of business hours.
Automated Data Quality Testing
Enforcing uniqueness, non-null, and range assertions before promoting data into production marts.
Git-Backed Version Control
100% of pipeline DAGs, SQL transformations, and configurations managed under version control with CI/CD.
Featured ETL/ELT Case Study
Automating end-to-end data pipelines for a fast-growing fintech wealth platform.
Apache Airflow & dbt Pipeline Engineering for Wealth Management
Built automated ELT pipelines using Apache Airflow and dbt ingesting financial transactions from core banking APIs, payment gateways, and CRM systems. Reduced pipeline runtime from 6 hours to 32 minutes while eliminating 100% of pipeline timeout failures.
Why Partner With Render Infotech?
Over 16+ years and 500+ successful deployments, we have established an engineering reputation in Bangalore for technical rigor, architectural transparency, and zero compromise on code quality.
- Dedicated In-House Engineers: Direct communication with senior specialists, not junior offshore intermediaries.
- 100% IP & Code Ownership: Full source code, database structures, and copyright ownership transferred upon milestone sign-off.
- Performance SLA Guarantee: Contractually committed speed benchmarks, security verification, and high-availability SLAs.
- Transparent Weekly Sprints: Live staging environments, progress demos, and clear milestone accounting.
Enterprise Performance Commitment
Every project we engineer is guaranteed to pass rigorous vulnerability scans, mobile responsiveness checks, and automated regression testing prior to production launch.
Bangalore Engineering Center
Kalyan Nagar, Bengaluru — Local Support & Global Standards
ETL / ELT Pipeline Development Services FAQs
Answers to common technical, pricing, and timeline questions regarding our ETL / ELT Pipeline Development Services services.
Ready to Architect Your Solution?
Connect directly with our senior technical architects in Bangalore for an architectural consultation, technology recommendation, and formal scope estimate within 24 hours.
Request a ETL / ELT Pipeline Development Services Proposal
Fill out your technical brief below to receive an architectural estimate within 24 hours.