
Enterprise Real-Time Data Pipeline Development in Bangalore
We architect fault-tolerant, high-throughput event streaming pipelines capable of ingesting, transforming, and delivering millions of events per second. Harness Apache Kafka, Apache Spark, and Flink for sub-second business intelligence and operational analytics.
Complete Data Pipeline Engineering Capabilities
Processing continuous data streams with high resilience and enterprise throughput guarantees.
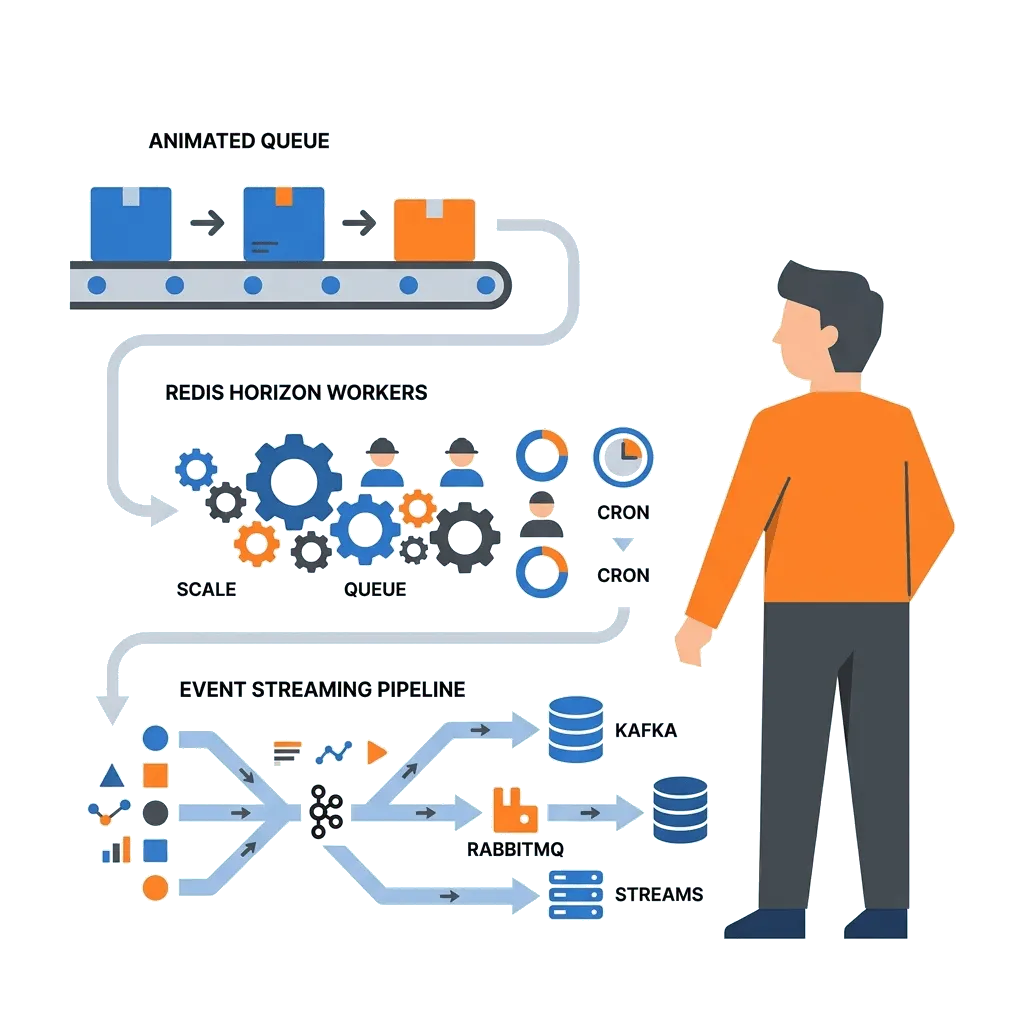
Distributed Event Streaming with Apache Kafka
Designing high-scale Kafka and Confluent clusters, partitioned topics, consumer groups, and schema registries handling terabytes daily.
Explore Distributed Event Streaming with Apache Kafka
Real-Time Stream Processing (Spark / Flink)
Stateful stream transformations, tumbling/sliding time-window aggregations, and anomaly detection using Apache Spark and Apache Flink.
Explore Real-Time Stream Processing (Spark / Flink)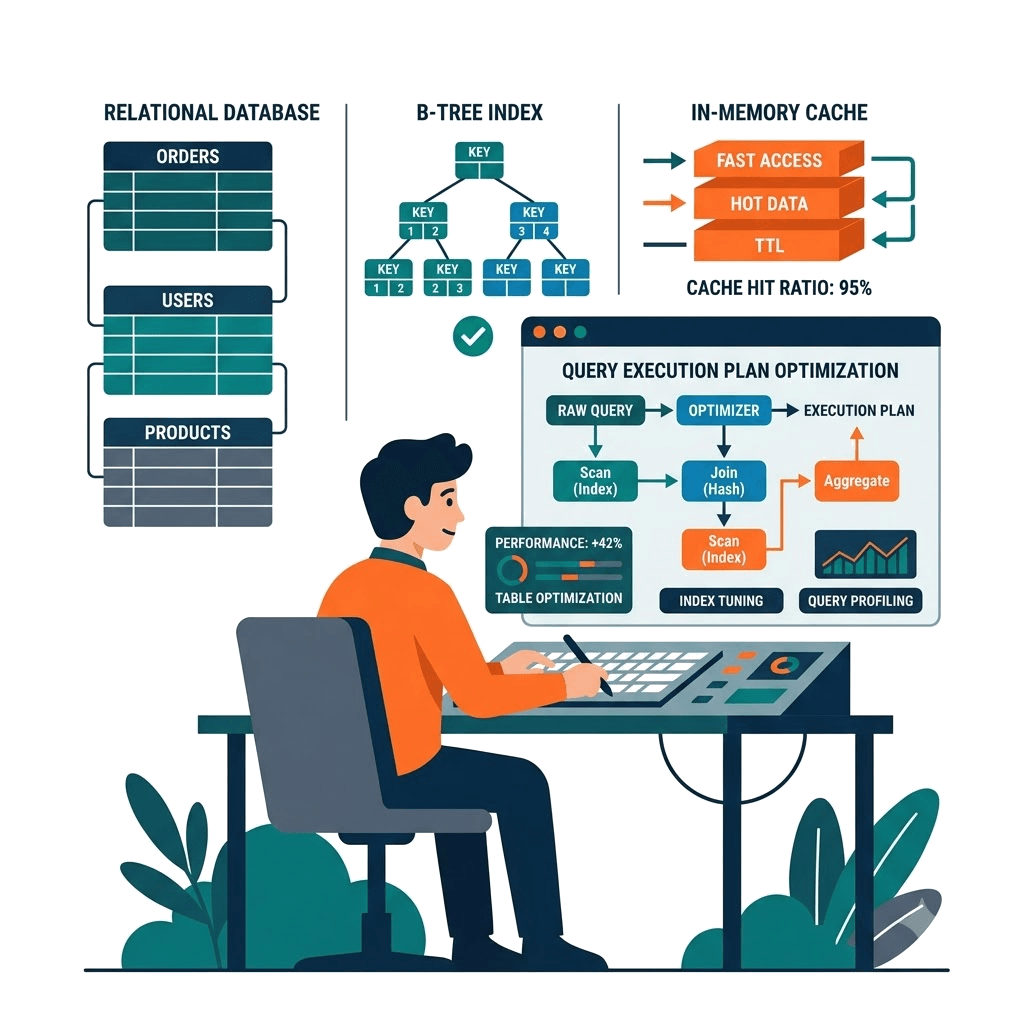
Change Data Capture (CDC) Architecture
Zero-impact transactional database replication using Debezium and Kafka Connect synchronizing OLTP stores into data warehouses in real time.
Explore Change Data Capture (CDC) Architecture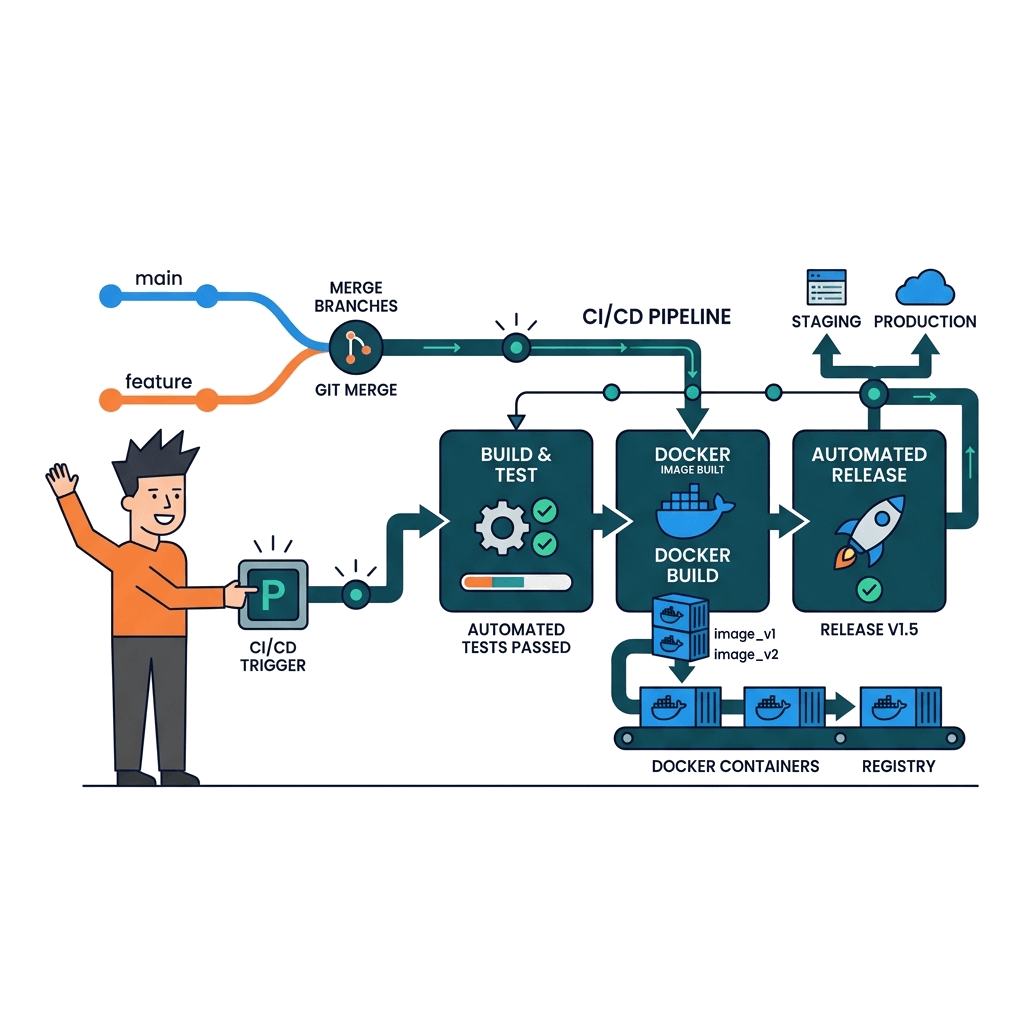
Cloud-Native Streaming (Kinesis / Pub/Sub)
Serverless event ingestion pipelines built on AWS Kinesis, Azure Event Hubs, and Google Cloud Pub/Sub with automatic autoscaling.
Explore Cloud-Native Streaming (Kinesis / Pub/Sub)
Schema Evolution & Governance
Enforcing Avro and Protobuf schemas via Confluent Schema Registry ensuring backwards and forwards payload compatibility.
Explore Schema Evolution & Governance
Pipeline Monitoring & Dead Letter Queues (DLQ)
Real-time pipeline telemetry, consumer lag tracking, Prometheus alerting, and automated routing of malformed events to DLQs.
Explore Pipeline Monitoring & Dead Letter Queues (DLQ)Our Streaming Pipeline Stack
Distributed brokers, stream compute engines, and schema management tooling.
Message Brokers
Stream Compute Engines
Connectors & CDC
Observability & Alerting
Our Pipeline Engineering Lifecycle
A systematic 6-step engineering methodology guaranteeing zero data loss and low latency.
Throughput & Latency Architecture Scoping
Profiling source data velocity, event payload size, ordering requirements, and end-to-end latency SLAs.
Schema Contract & Serialization Design
Defining Avro/Protobuf event models and establishing compatibility policies in the Schema Registry.
Cluster Provisioning & Topic Partitioning
Sizing broker nodes, storage IOPS, and calculating optimal topic partition counts for maximum parallelism.
Stream Processing Logic Implementation
Authoring Spark Structured Streaming or Flink jobs with stateful windowing, deduplication, and filtering.
Resilience, Chaos & Backpressure Testing
Testing broker failures, network partitions, sudden 10x traffic spikes, and validating consumer lag recovery.
Production Deployment & Observability
Deploying production pipelines with automated autoscaling, consumer lag alerts, and DLQ routing.
Enterprise Pipeline Standards
Guaranteed exactly-once semantics, high resilience, and zero data loss.
Exactly-Once Processing Semantics
Enforcing idempotent producers and transactional commits to guarantee zero duplicated data records.
Sub-Second Ingestion Latency
P99 stream processing latency guaranteed under 500ms from source generation to target datastore.
Zero Data Loss Architecture
Configuring replication factors >= 3 and min.insync.replicas >= 2 across multi-availability-zone clusters.
Automated Dead Letter Queuing
Isolating poisoned or malformed event payloads without halting real-time consumer execution.
Consumer Lag SLA Monitoring
Triggering automated alerts if consumer group lag exceeds 2 seconds of traffic volume.
End-to-End Encryption in Transit
Securing all broker-to-client communication with TLS/SSL encryption and SASL SCRAM-512 authentication.
Featured Real-Time Pipeline Case Study
Building a 50,000 events/second real-time telemetry pipeline for an IoT mobility provider.
Apache Kafka & Spark Streaming Pipeline for Connected Vehicles
Designed and deployed an enterprise Kafka and Spark Streaming ingestion pipeline handling 50,000 GPS and battery telemetry events per second. Reduced alert latency from 15 minutes to 350 milliseconds, enabling instantaneous emergency incident routing.
Why Partner With Render Infotech?
Over 16+ years and 500+ successful deployments, we have established an engineering reputation in Bangalore for technical rigor, architectural transparency, and zero compromise on code quality.
- Dedicated In-House Engineers: Direct communication with senior specialists, not junior offshore intermediaries.
- 100% IP & Code Ownership: Full source code, database structures, and copyright ownership transferred upon milestone sign-off.
- Performance SLA Guarantee: Contractually committed speed benchmarks, security verification, and high-availability SLAs.
- Transparent Weekly Sprints: Live staging environments, progress demos, and clear milestone accounting.
Enterprise Performance Commitment
Every project we engineer is guaranteed to pass rigorous vulnerability scans, mobile responsiveness checks, and automated regression testing prior to production launch.
Bangalore Engineering Center
Kalyan Nagar, Bengaluru — Local Support & Global Standards
Real-Time Data Pipeline Development Services FAQs
Answers to common technical, pricing, and timeline questions regarding our Real-Time Data Pipeline Development Services services.
Ready to Architect Your Solution?
Connect directly with our senior technical architects in Bangalore for an architectural consultation, technology recommendation, and formal scope estimate within 24 hours.
Request a Real-Time Data Pipeline Development Services Proposal
Fill out your technical brief below to receive an architectural estimate within 24 hours.