
Big Data Processing & Data Engineering in Bangalore
Transform fragmented corporate data into high-throughput, analytics-ready assets. Render Infotech engineers petabyte-scale real-time streaming pipelines, modern Snowflake & Databricks lakehouses, automated ETL/ELT workflows, and sub-second BI analytics.
High-throughput data engineering built for zero data loss and sub-second query latency.
Eliminate Data Silos with Scalable, Real-Time Data Pipelines
Modern enterprises drown in data while starving for real-time insights. Traditional monolithic databases choke under streaming volumes, resulting in stale business reports, slow dashboard queries, and ballooning cloud warehouse bills.
Render Infotech is Bangalore's premier data engineering and big data consulting partner. We design resilient event-driven architectures, automated dbt transformation models, and cost-optimized lakehouses that deliver fresh, trustworthy data to decision-makers, machine learning models, and customer applications in real-time.
Real-Time Streaming
Low-latency Kafka and Spark streaming pipelines ingest and process high-frequency telemetry, clickstreams, and IoT events.
Cloud Warehousing
Architected on Snowflake, BigQuery, and Databricks with automated query pruning and FinOps compute governance.
Automated ELT & dbt
Version-controlled SQL transformations, automated data testing, and CI/CD pipelines orchestrated by Apache Airflow.
Security & DPDP
Column-level masking, automated PII scrubbing, encrypted storage, and audit logs compliant with global data laws.
Comprehensive Big Data & Engineering Services
From high-frequency streaming pipelines and cloud lakehouses to automated dbt transformation models and enterprise data governance.
Large-Scale Batch & Stream Processing
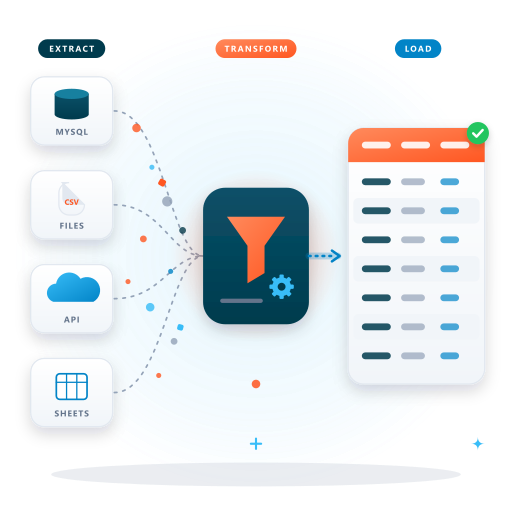
Architecting fault-tolerant event ingestion pipelines using Apache Kafka, Apache Spark, and Flink capable of processing millions of events per second with zero message loss.
Explore Streaming Pipelines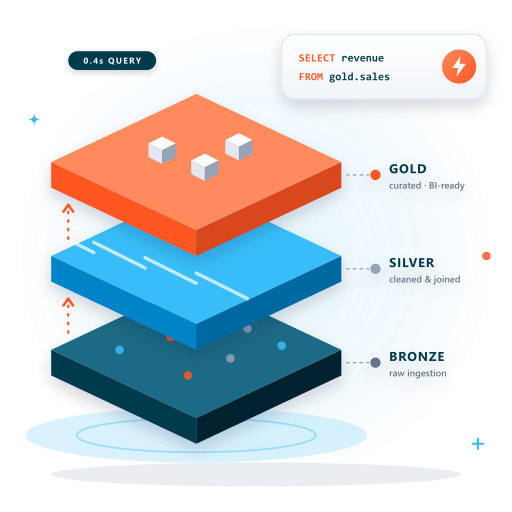
Snowflake & Cloud Data Warehousing
Designing scalable multi-cluster shared data architectures on Snowflake, AWS Redshift, and Google BigQuery with automated schema evolution and FinOps query cost controls.
Explore Snowflake Solutions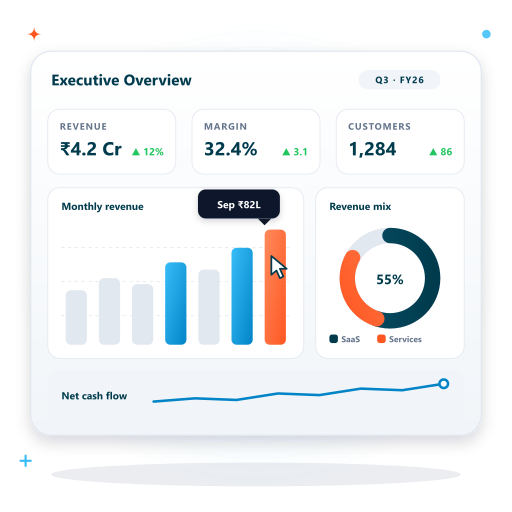
Modern Data Lakehouse Engineering
Unifying unstructured data lakes with relational warehouses using Delta Lake, Apache Iceberg, and Databricks for reliable ACID transactions and seamless ML feature engineering.
Explore Lakehouse Design
Automated ETL / ELT Pipeline Development
Building production-grade data pipelines orchestrated by Apache Airflow, Prefect, and dbt with automated data quality assertions, schema testing, and error-quarantine queues.
Explore Pipeline Development
Data Governance, Quality & Compliance
Enforcing automated data cataloging, metadata lineage tracking, dynamic PII masking, and full regulatory compliance with Indian DPDP Act, GDPR, and HIPAA frameworks.
Explore Data Governance
BI Analytics & Real-Time Dashboards
Delivering sub-second interactive dashboards on Looker, Power BI, and Tableau powered by clean semantic layers and pre-aggregated analytical data marts.
Explore BI & AnalyticsEnterprise-Grade Big Data Technologies
We build on battle-tested open-source frameworks and market-leading cloud data warehouse engines.
Streaming & Ingestion
- Apache Kafka & Confluent
- Apache Spark & PySpark
- Apache Flink Event Streams
- AWS Kinesis & EventBridge
- Debezium CDC Pipelines
Warehouses & Lakehouses
- Snowflake Data Cloud
- Databricks & Delta Lake
- AWS Redshift Serverless
- Google BigQuery
- Apache Iceberg Open Table
Orchestration & Modeling
- dbt (data build tool)
- Apache Airflow DAGs
- Prefect Workflow Orchestration
- Great Expectations Testing
- Terraform & Infrastructure as Code
Analytics & Storage
- Looker & Looker Studio
- Microsoft Power BI & DAX
- AWS S3 & Azure ADLS Gen2
- PostgreSQL & TimescaleDB
- Redis Cache & Vector Stores
The Modern Enterprise Data Pipeline Lifecycle
Ingestion & CDC
Continuous change data capture (CDC) and batch ingestion from APIs, IoT sensors, operational SQL databases, and SaaS applications.
dbt Orchestration
Version-controlled SQL transformations, automated data validation tests, schema evolution handling, and Airflow DAG scheduling.
Lakehouse Storage
Organized bronze/silver/gold medallion architecture on Snowflake or Databricks with clustering keys and FinOps cost tuning.
Consumption & BI
Real-time semantic layers powering Looker dashboards, machine learning model training features, and customer-facing analytical APIs.
High-Impact Industry Data Solutions
Fintech & Banking
Sub-second fraud detection, multi-source ledger reconciliation, and real-time regulatory compliance reporting.
Retail & E-Commerce
Omni-channel Customer 360 views, dynamic pricing algorithms, and real-time warehouse inventory synchronization.
Healthcare & Pharma
HIPAA-compliant EHR clinical data integration, patient telemetry processing, and diagnostic research pipelines.
Supply Chain & IoT
High-frequency GPS fleet telemetry, automated arrival predictions, and predictive equipment maintenance alerts.
Faster Data Availability
Replacing stale overnight batches with real-time stream ingestion.
Cloud Cost Savings
FinOps query clustering and auto-suspend warehouse policies.
Pipeline Reliability
Automated error quarantine and self-healing Airflow task retries.
Audit Compliance
Strict column-level PII masking and automated lineage tracking.
Frequently Asked Questions on Data Engineering
Ready to Architect a Scalable Cloud Data Platform?
Connect directly with our Lead Data Architects in Bangalore for a complimentary 30-minute architectural review of your current data pipelines, warehouse latency, and FinOps costs.
Request Data Engineering Consultation
Fill in your details below and a senior data architect will respond within 2 hours.