
Always On: Managed Cloud Infrastructure & 24/7 SRE in Bangalore
We provide round-the-clock Site Reliability Engineering (SRE) and managed cloud infrastructure operations across AWS, Azure, and GCP. Protect uptime, resolve incidents with a guaranteed sub-15 minute response SLA, and automate routine operational tasks.
Complete Managed Cloud Operations Capabilities
Ensuring flawless system availability, rapid incident resolution, and continuous optimization.
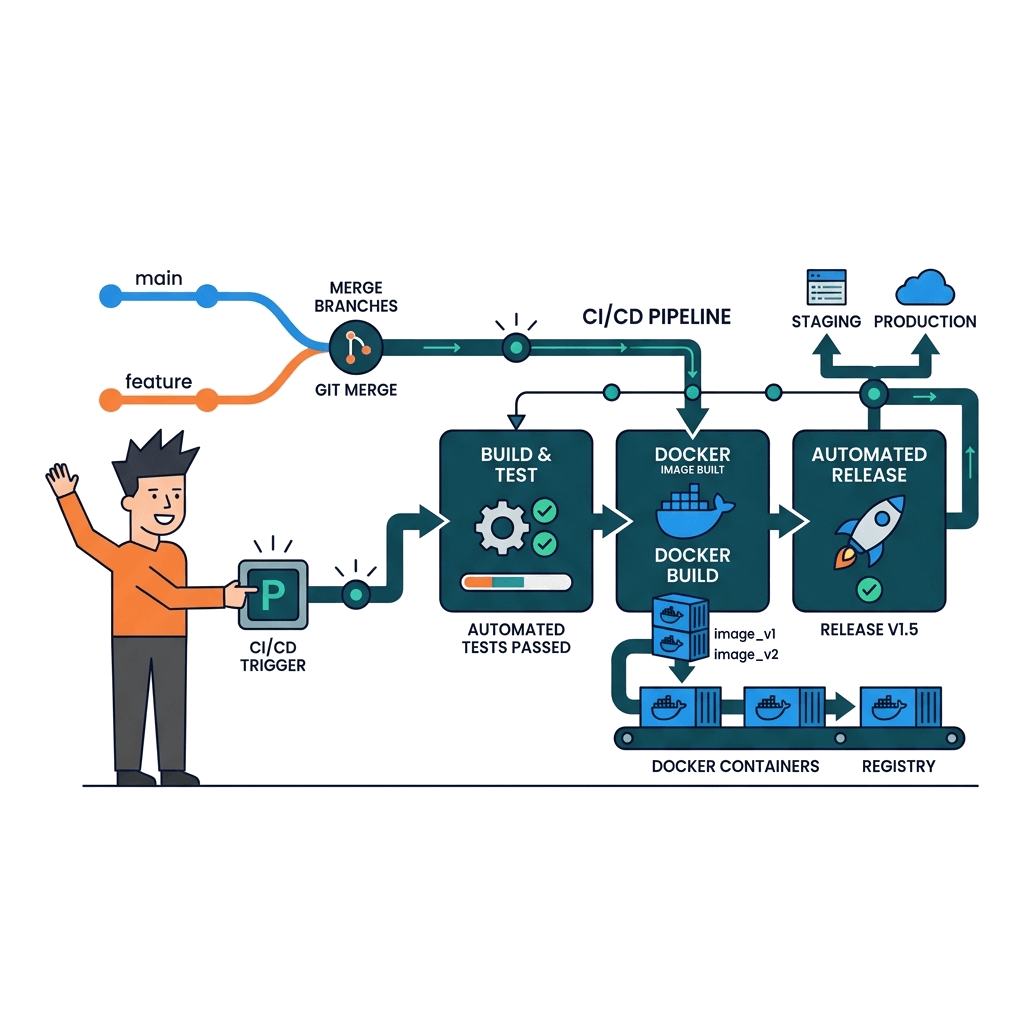
24/7/365 Incident Management & Response
Dedicated SRE engineers monitoring your infrastructure around the clock with guaranteed sub-15 minute response times for high-severity issues.
Explore 24/7/365 Incident Management & Response
Full-Stack Observability & Telemetry
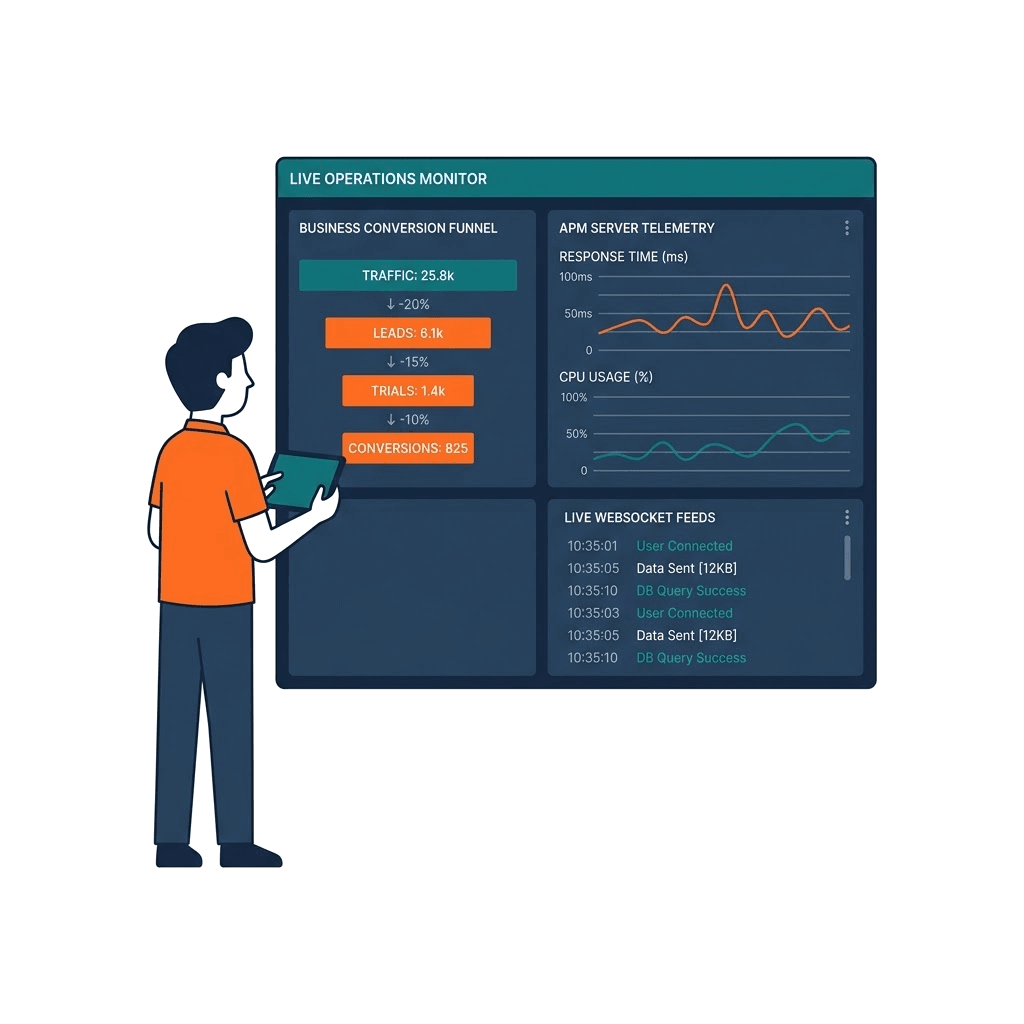
Implementing unified metrics, distributed tracing, and centralized log aggregation with Datadog, Prometheus, Grafana, and OpenTelemetry.
Explore Full-Stack Observability & Telemetry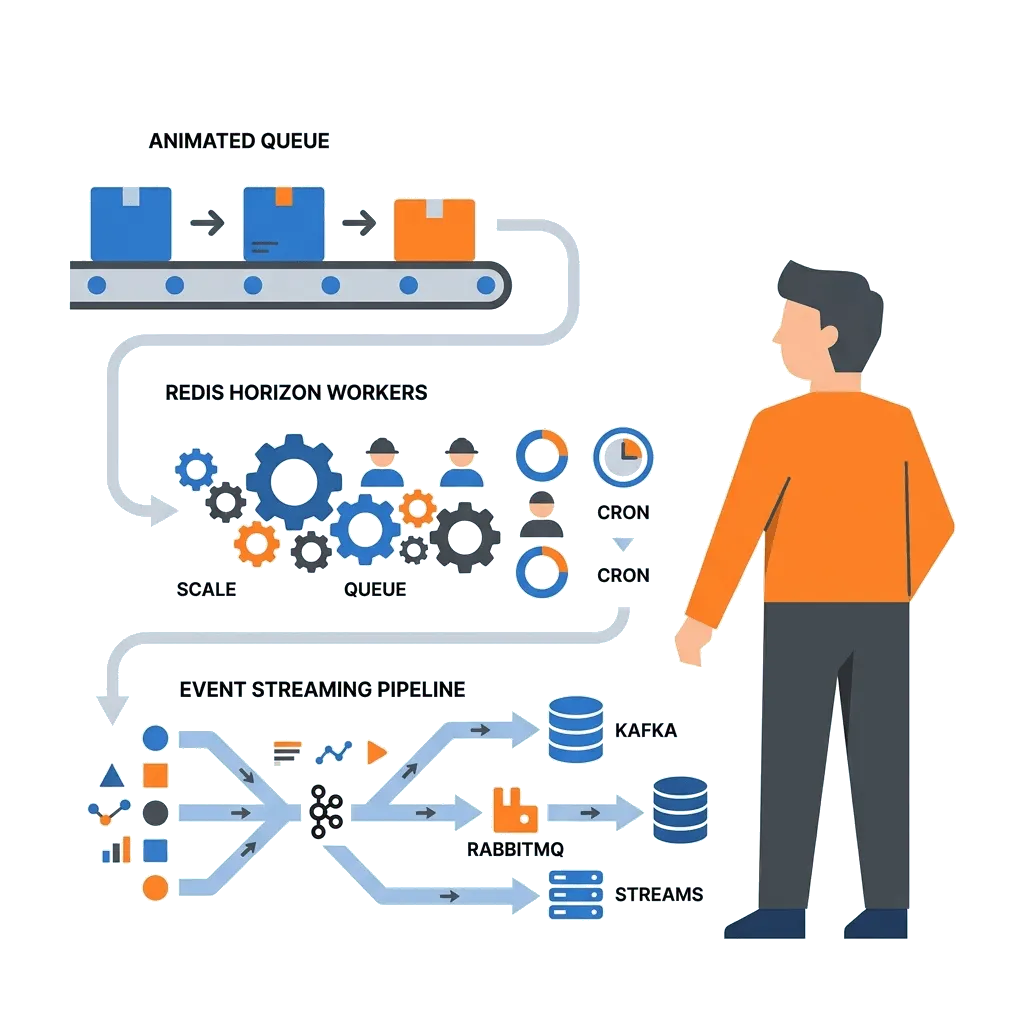
Automated Self-Healing & Auto-Remediation
Building event-driven automation runbooks that automatically restart failed pods, clear stuck queues, and scale instances before outages occur.
Explore Automated Self-Healing & Auto-Remediation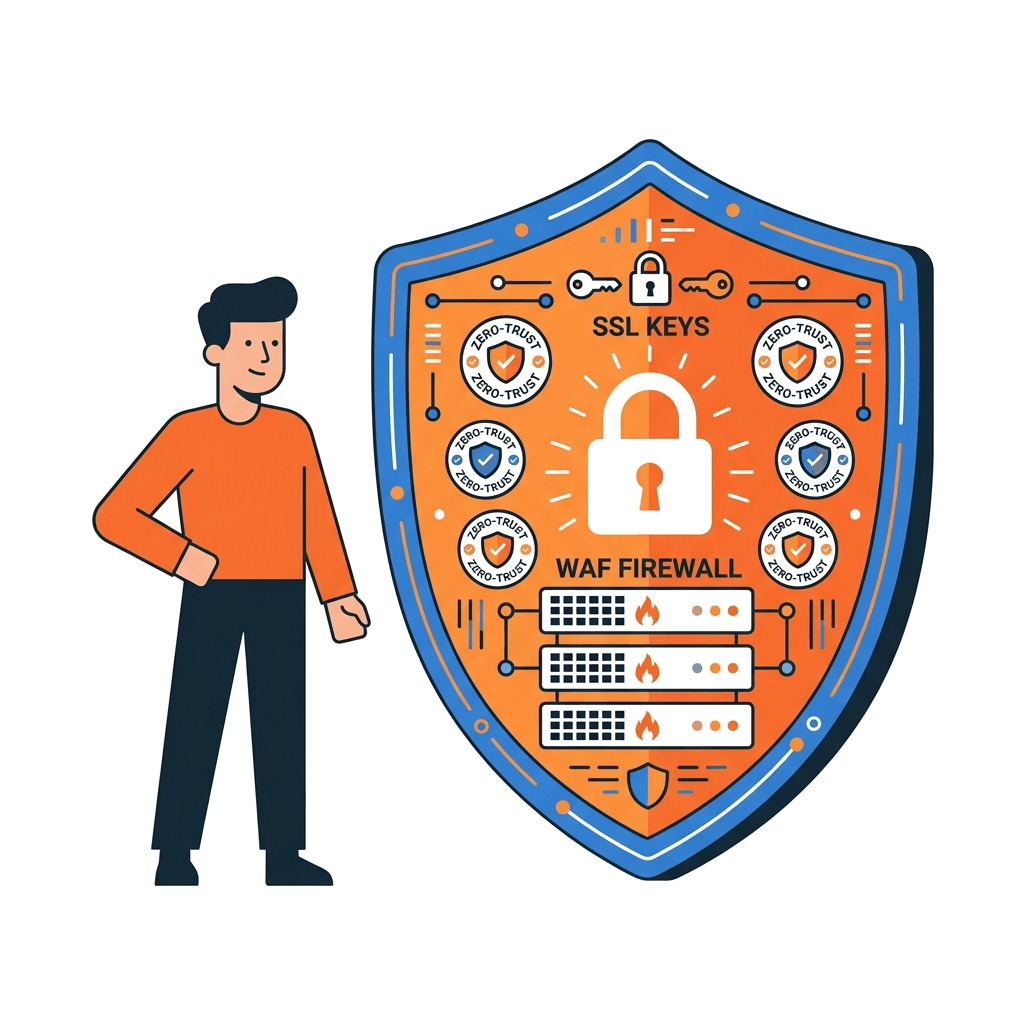
Patch Management & OS Hardening
Scheduled zero-downtime rolling operating system patches, kernel security updates, and vulnerability remediation across all cloud servers.
Explore Patch Management & OS Hardening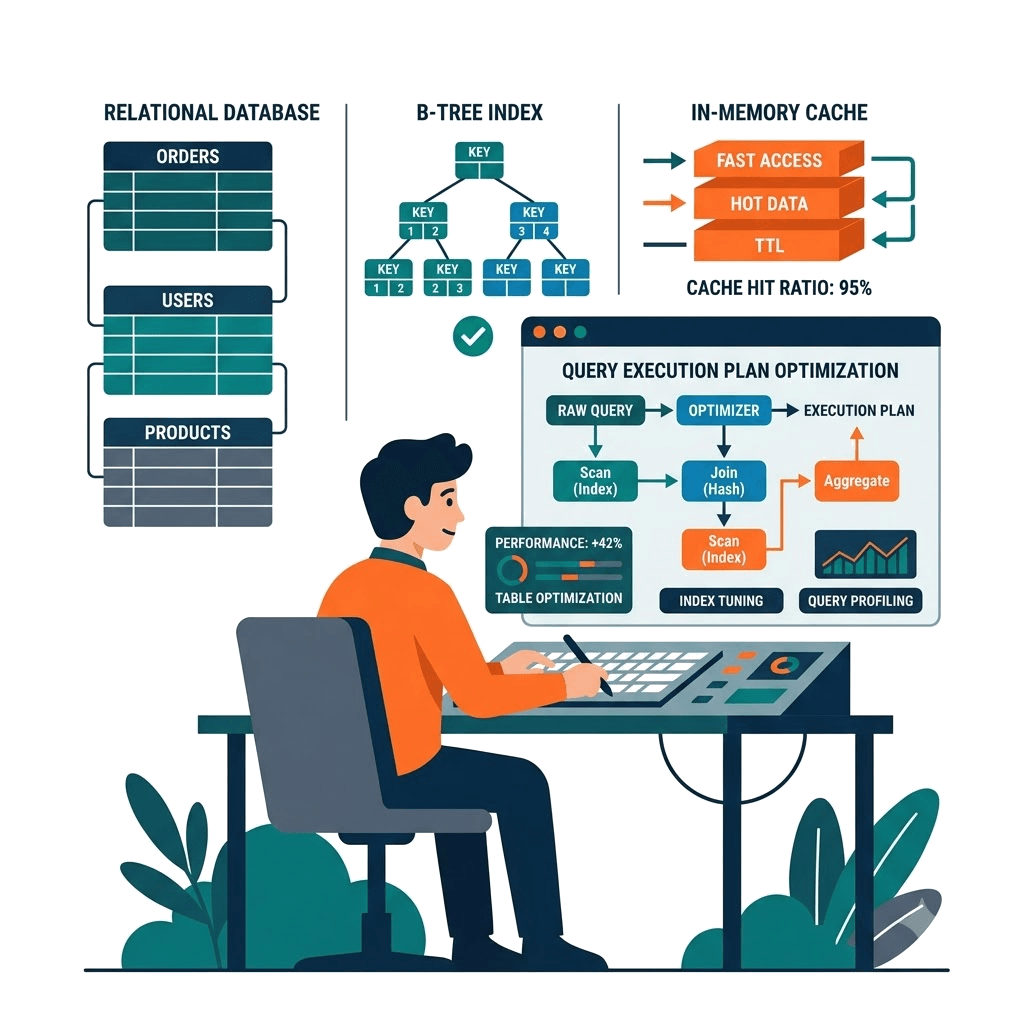
Backup & Automated Disaster Recovery (DR)
Automating cross-region snapshots, immutable backups, and conducting routine quarterly DR failover drills with verified RTO/RPO metrics.
Explore Backup & Automated Disaster Recovery (DR)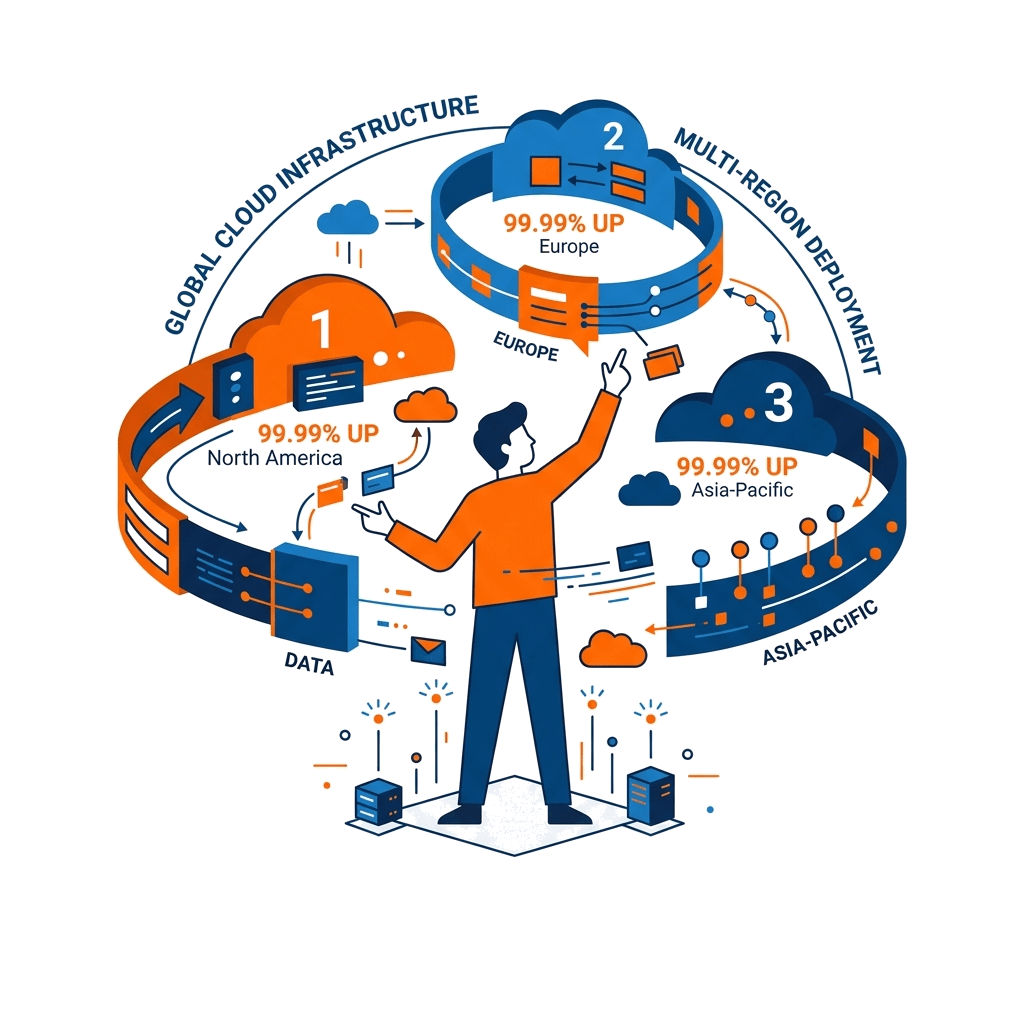
Capacity Planning & FinOps Governance
Proactive resource forecasting, CPU/memory scaling recommendations, and monthly cloud cost audits keeping your cloud budget predictable.
Explore Capacity Planning & FinOps GovernanceOur SRE & Operations Toolset
Incident paging platforms, APM monitoring suites, and automation runbooks.
Incident & On-Call
Observability & APM
Automation & Runbooks
Security & Backups
Our Managed SRE Lifecycle
A proven continuous operations framework delivering stability and resilience.
NOC Onboarding & Runbook Ingestion
Ingesting architecture documentation, standard operating procedures (SOPs), escalations, and alert thresholds.
Observability & SLI/SLO Instrumentation
Instrumenting Datadog or Prometheus metrics, defining Service Level Indicators (SLIs) and Error Budgets.
Alert Fatigue Elimination & Tuning
Refining alert thresholds to eliminate false positives, ensuring only actionable anomalies page on-call SREs.
Automated Self-Healing Setup
Implementing automated restart policies, auto-remediation scripts, and scheduled maintenance tasks.
24/7/365 Active Operations & Paging
Managing round-the-clock shift rotations responding to infrastructure alarms under strict SLA time limits.
Continuous Post-Mortems & FinOps Reviews
Conducting blameless incident post-mortems and monthly architecture optimization reviews.
Enterprise SRE Standards
Rigorous response times, high availability, and operational discipline.
Sub-15 Minute Sev-1 Response SLA
Certified SRE engineers actively investigating critical infrastructure incidents within 15 minutes.
99.99% Guaranteed Platform Uptime
Engineering multi-zone high availability backed by strict Service Level Agreements.
Zero Alert Fatigue Guarantee
Continuous tuning of monitoring thresholds so alerts represent genuine operational emergencies.
Blameless Post-Mortem Reviews
Every Sev-1 incident documented with a blameless post-mortem report and permanent prevention tickets.
Tested Quarterly DR Recovery Drills
Validating cross-region disaster recovery restores quarterly to verify Recovery Time Objectives (RTO).
Strict Least-Privilege Access
All SRE access mediated through secure bastion hosts, temporary credentials, and audit-logged sessions.
Featured Managed SRE Case Study
Delivering 24/7 managed infrastructure operations for an enterprise B2B fintech provider.
Round-the-Clock Managed SRE for Financial Platform
Took over 24/7 cloud infrastructure operations for an enterprise fintech platform processing $20M in daily transactions across AWS and Kubernetes. Reduced Sev-1 incident count by 78% through automated self-healing runbooks and maintained 99.99% uptime over 18 months.
Why Partner With Render Infotech?
Over 16+ years and 500+ successful deployments, we have established an engineering reputation in Bangalore for technical rigor, architectural transparency, and zero compromise on code quality.
- Dedicated In-House Engineers: Direct communication with senior specialists, not junior offshore intermediaries.
- 100% IP & Code Ownership: Full source code, database structures, and copyright ownership transferred upon milestone sign-off.
- Performance SLA Guarantee: Contractually committed speed benchmarks, security verification, and high-availability SLAs.
- Transparent Weekly Sprints: Live staging environments, progress demos, and clear milestone accounting.
Enterprise Performance Commitment
Every project we engineer is guaranteed to pass rigorous vulnerability scans, mobile responsiveness checks, and automated regression testing prior to production launch.
Bangalore Engineering Center
Kalyan Nagar, Bengaluru — Local Support & Global Standards
Managed Cloud Infrastructure & 24/7 SRE FAQs
Answers to common technical, pricing, and timeline questions regarding our Managed Cloud Infrastructure & 24/7 SRE services.
Ready to Architect Your Solution?
Connect directly with our senior technical architects in Bangalore for an architectural consultation, technology recommendation, and formal scope estimate within 24 hours.
Request a Managed Cloud Infrastructure & 24/7 SRE Proposal
Fill out your technical brief below to receive an architectural estimate within 24 hours.